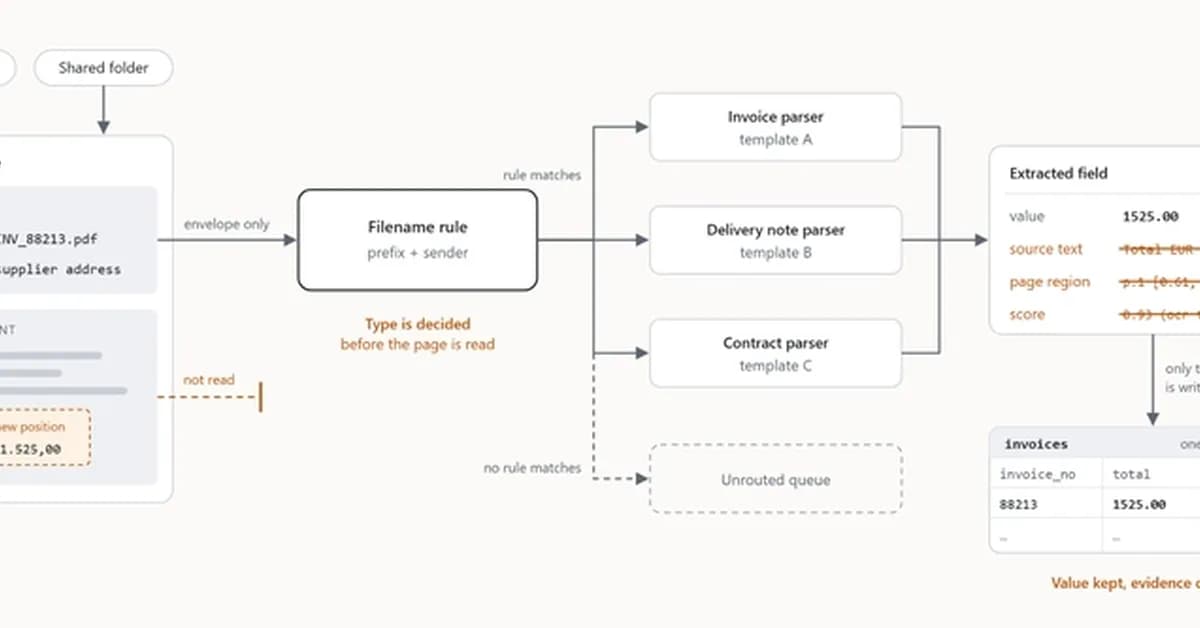
Document processing pipelines often struggle when document formats change unexpectedly, leading to inaccurate data extraction. A new approach emphasizes retaining detailed information about how data was extracted, including the original text, its location on the page, the model used, and confidence scores, all stored within MongoDB Atlas. This allows for better error detection, review prioritization, and ultimately, more reliable data extraction from diverse and evolving document types.
Read the full article at DEV Community
Want to create content about this topic? Use Nemati AI tools to generate articles, social posts, and more.
Views2
Ali NematiBlogUI.author_articles