The research paper introduces "Agentic Evolution Strategy Optimization" (ESOpt), a novel approach for fine-tuning large language models (LLMs) in the context of reinforcement learning. This method leverages evolutionary strategies to optimize model parameters based on their performance as agents within specific environments. Here's an overview and key insights from the paper:
Core Concept
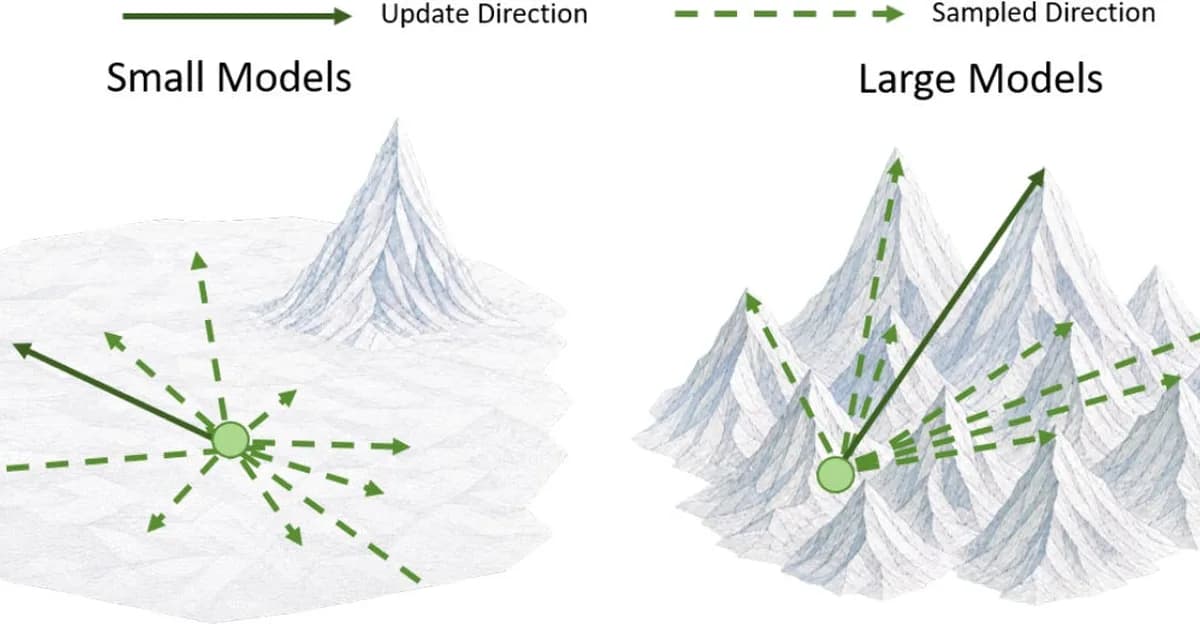
Agentic ESOpt works by sampling perturbations around a base model, evaluating these perturbed models (agents) in an environment, and updating the base model towards parameter configurations that yield higher rewards.
- Perturbation Magnitude: The algorithm uses a cosine decay schedule for sigma (perturbation standard deviation), starting with large values to explore broadly and gradually decreasing to refine parameters finely.
- Population Sizing: Contrary to conventional wisdom, stronger models require smaller populations due to the geometry of perturbation space. Stronger models are already well-positioned, making extra samples redundant.
Key Insights
- Exploration vs Exploitation Trade-off: The cosine decay schedule addresses this trade-off by encouraging broad exploration early on and focused refinement later.
- Simplicity and Robustness: Agentic ESOpt's simplicity (few moving parts, minimal hyper
Read the full article at AIModels.fyi
Want to create content about this topic? Use Nemati AI tools to generate articles, social posts, and more.
Views48
On this page

Ali NematiBlogUI.author_articles