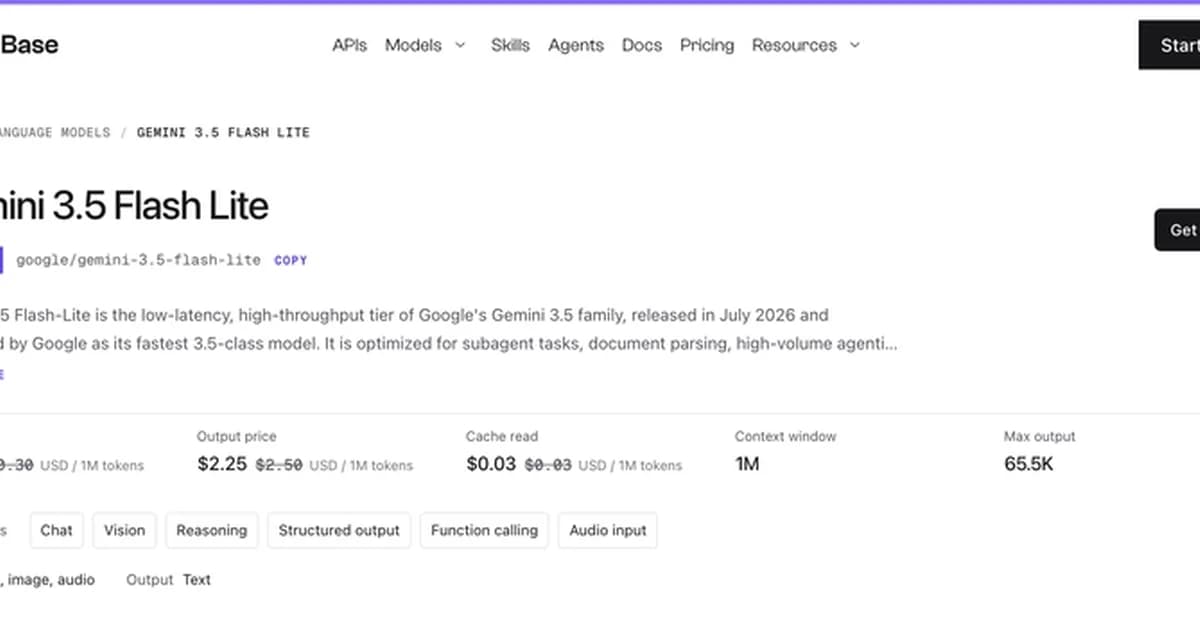
A strategy for optimizing LLM costs involves using a cheaper model for initial responses and escalating to a more powerful model only when necessary, identified by an 'escalate' flag in the cheap model's output. This approach, demonstrated with Gemini 3.5 Flash-Lite and Claude Sonnet 5.5, significantly reduced costs in test runs by handling simple queries efficiently. Businesses should analyze their user query mix to determine the optimal routing strategy and monitor escalated requests for quality assurance.
Read the full article at DEV Community
Want to create content about this topic? Use Nemati AI tools to generate articles, social posts, and more.
Views9

Ali NematiBlogUI.author_articles