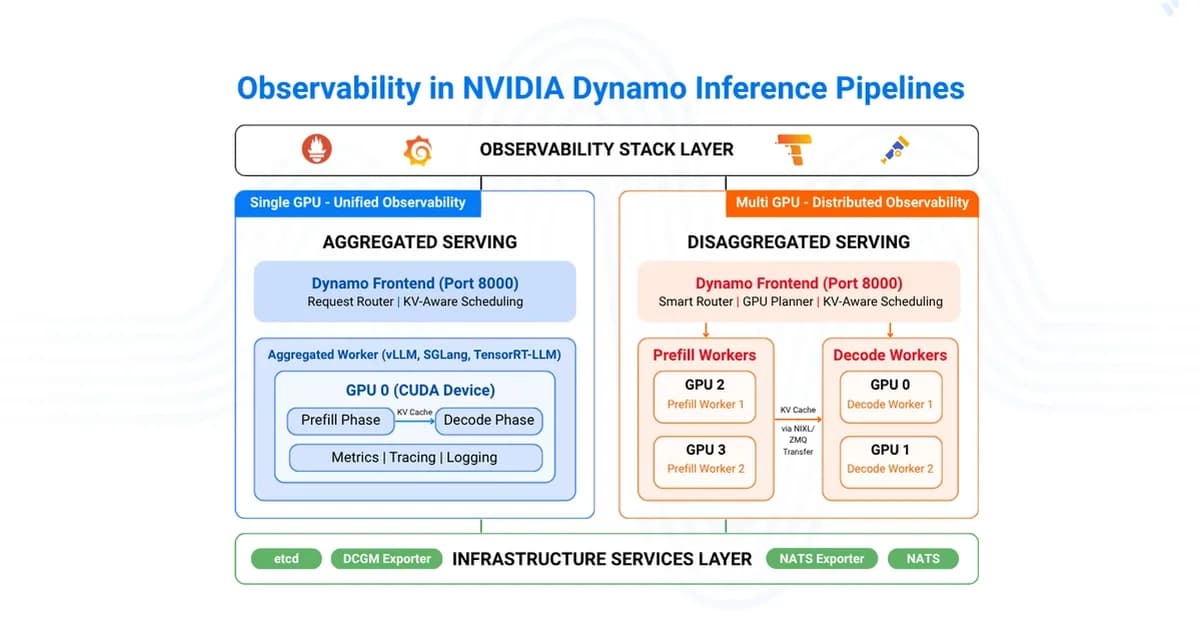
This guide details how to deploy an aggregated NVIDIA Dynamo serving setup with full observability enabled for single-GPU environments. It provides a complete bash script that sources configuration files to activate JSON logging and OpenTelemetry tracing while launching both the frontend and vLLM worker services. Users can then verify the integration by accessing specific metrics endpoints and monitoring dashboards like Grafana, Tempo, and Prometheus to track performance across the entire system.
Read the full article at DEV Community
Want to create content about this topic? Use Nemati AI tools to generate articles, social posts, and more.
Views39
Tags

Ali NematiBlogUI.author_articles