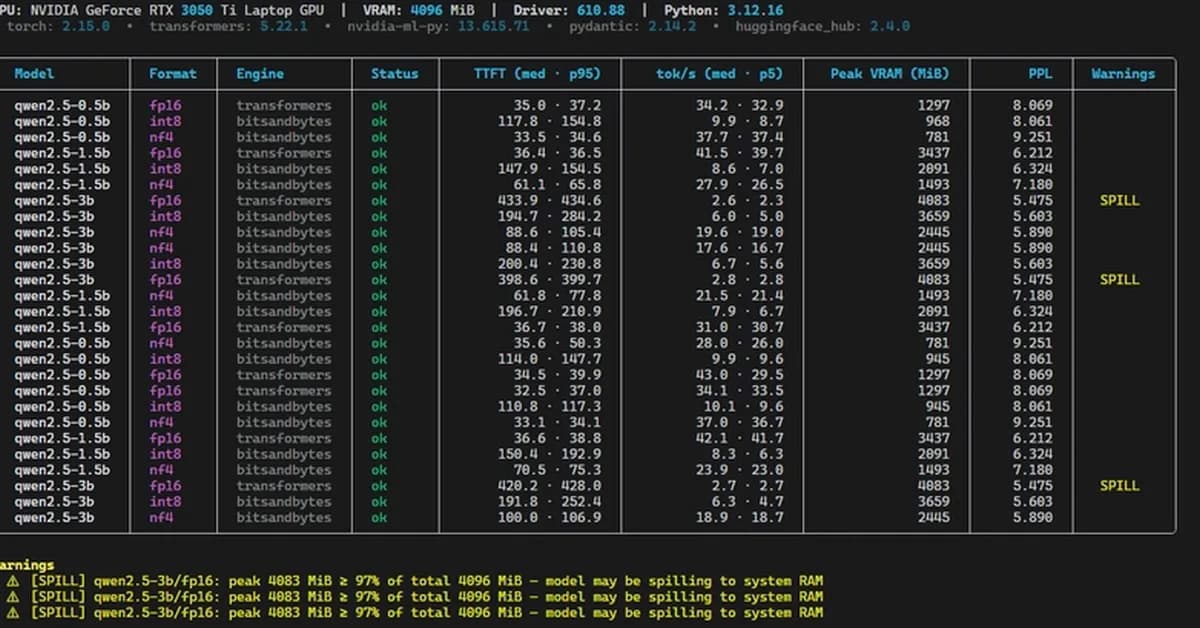
A new benchmarking tool called quantbench has been developed to evaluate Large Language Model quantization on hardware with limited VRAM, specifically 4GB. It addresses methodological challenges by controlling execution variables and using multi-domain quality metrics. This research is vital for developers working with constrained hardware, offering insights into whether to use smaller models at native precision or larger, quantized models for better performance and quality on budget systems.
Read the full article at DEV Community
Want to create content about this topic? Use Nemati AI tools to generate articles, social posts, and more.
Views8

Ali NematiBlogUI.author_articles