Knowledge Distillation: A Comprehensive Guide
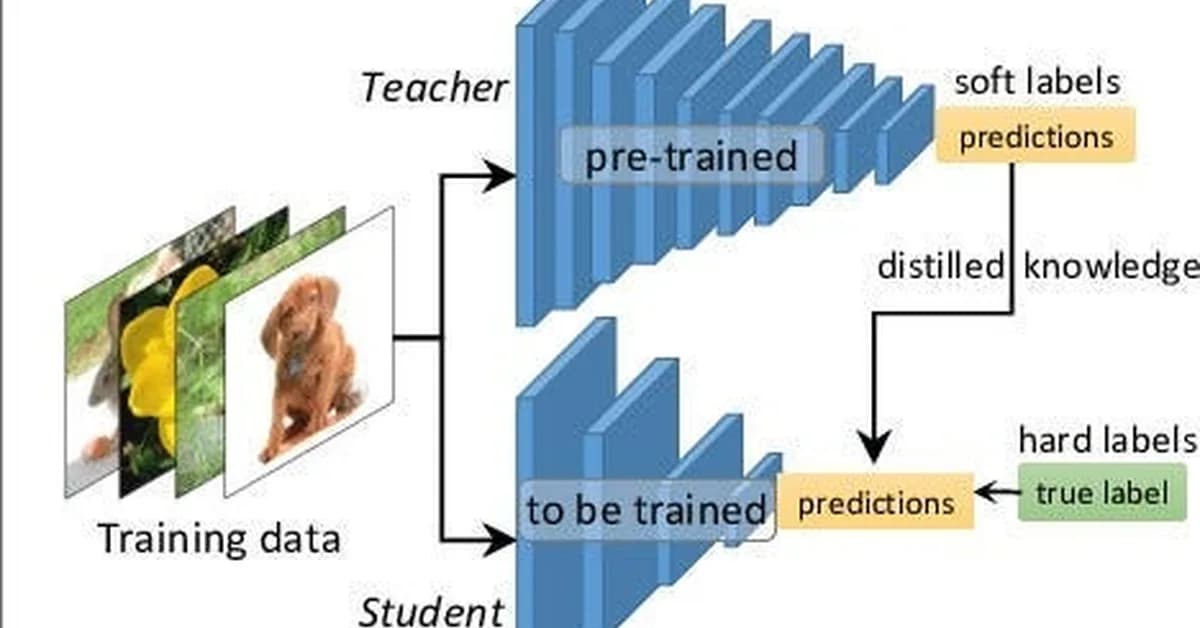
Knowledge distillation is a technique used in machine learning to transfer knowledge from a larger, more complex "teacher" model to a smaller, simpler "student" model. The goal is to improve the performance of the student model while reducing its computational cost and resource requirements.
Standard Softmax Function
Let's start with the standard softmax function. Given a vector of logits ( z ) for ( C ) classes:
[ z = [z_1, z_2, ..., z_C] ]
The probability assigned to class ( i ) is given by:
[ p_i = \frac{e^{z_i}}{\sum_{j=1}^C e^{z_j}} ]
The class with the largest logit receives the highest probability.
Temperature-Scaled Softmax
In knowledge distillation, a temperature ( T > 0 ) is introduced to soften the probability distribution:
[ p_i = \frac{e^{z_i / T}}{\sum_{j=1}^C e^{z_j / T}} ]
- When ( T = 1 ), this reduces to the standard softmax.
- Increasing ( T )
Read the full article at Towards AI - Medium
Want to create content about this topic? Use Nemati AI tools to generate articles, social posts, and more.