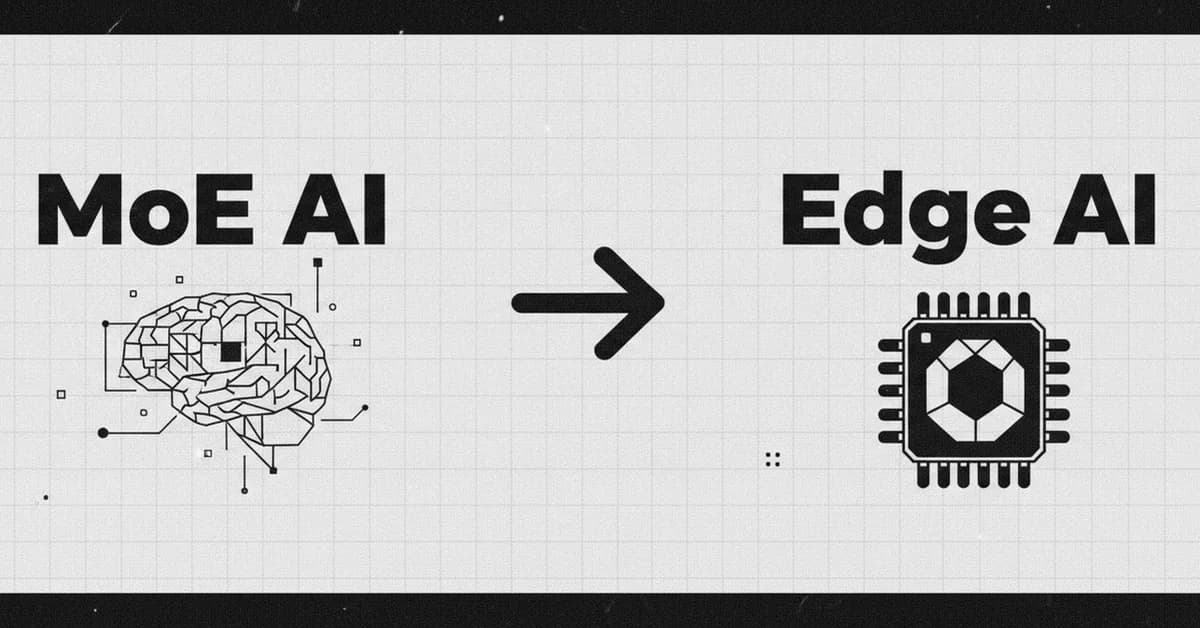
Mixture of Experts (MoE) models allow for the creation of large neural networks with a high total parameter count, but only a subset of 'experts' are activated for any given input. This sparse activation significantly reduces the computational load for each token, making complex models more feasible for resource-constrained environments like mobile devices. MoE refers to the model's architecture, distinct from 'edge computing' which describes where computation occurs.
Read the full article at DEV Community
Want to create content about this topic? Use Nemati AI tools to generate articles, social posts, and more.
Views44
Ali NematiBlogUI.author_articles