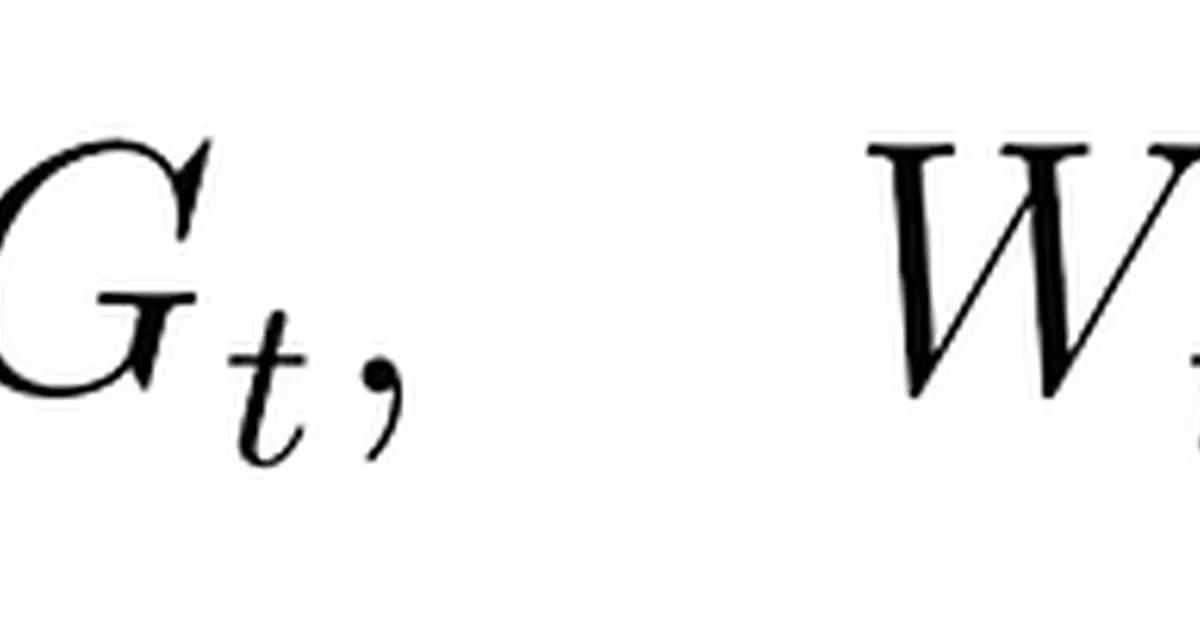
Muon has emerged as a new AI training optimizer that significantly outperforms traditional methods like Adam by orthogonalizing updates. It replaces standard momentum with an orthogonal matrix derived from Newton-Schulz iterations, resulting in faster training times and improved compute efficiency, evidenced by speed records on benchmarks and adoption by major AI models. This approach addresses limitations in Adam by considering the matrix structure of weight updates, offering a more efficient path to model training.
Read the full article at Towards AI - Medium
Want to create content about this topic? Use Nemati AI tools to generate articles, social posts, and more.
Views42

Ali NematiBlogUI.author_articles