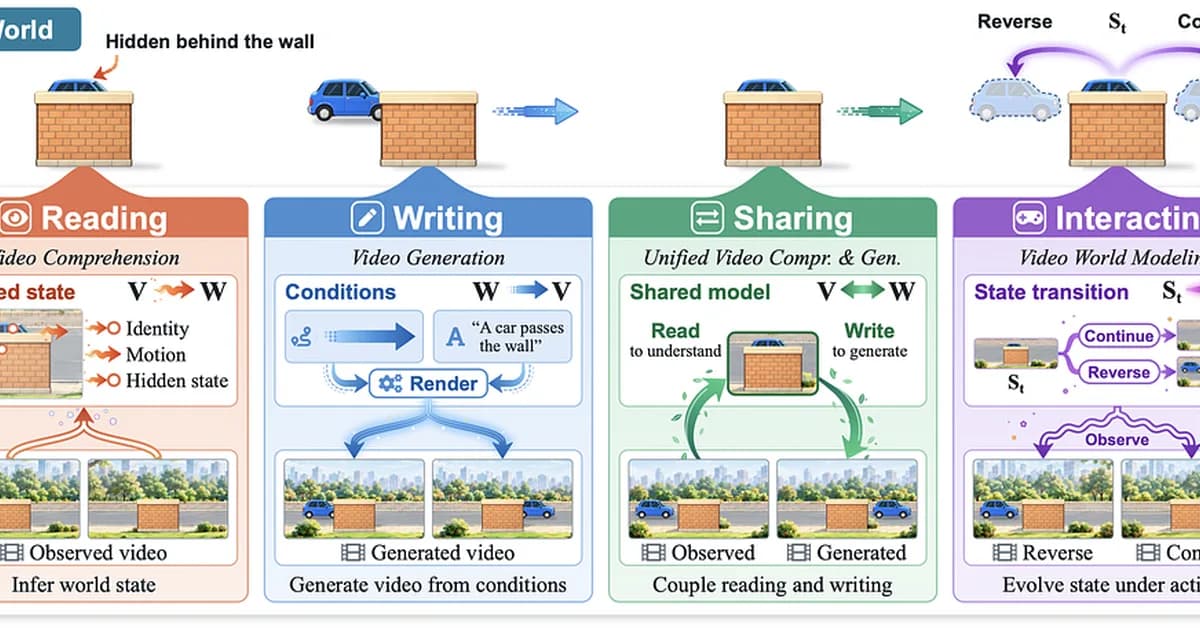
A new framework proposes viewing video as a partial observation of an evolving world, connecting video understanding, generation, unified models, and world models through four core operations: reading (video to world), writing (world to video), sharing (unified models), and interacting (world advancement under actions). The key challenge is demonstrating a model tracks the world behind the frames, not just renders convincing visuals.
Read the full article at Towards AI - Medium
Want to create content about this topic? Use Nemati AI tools to generate articles, social posts, and more.
Views59

Ali NematiBlogUI.author_articles