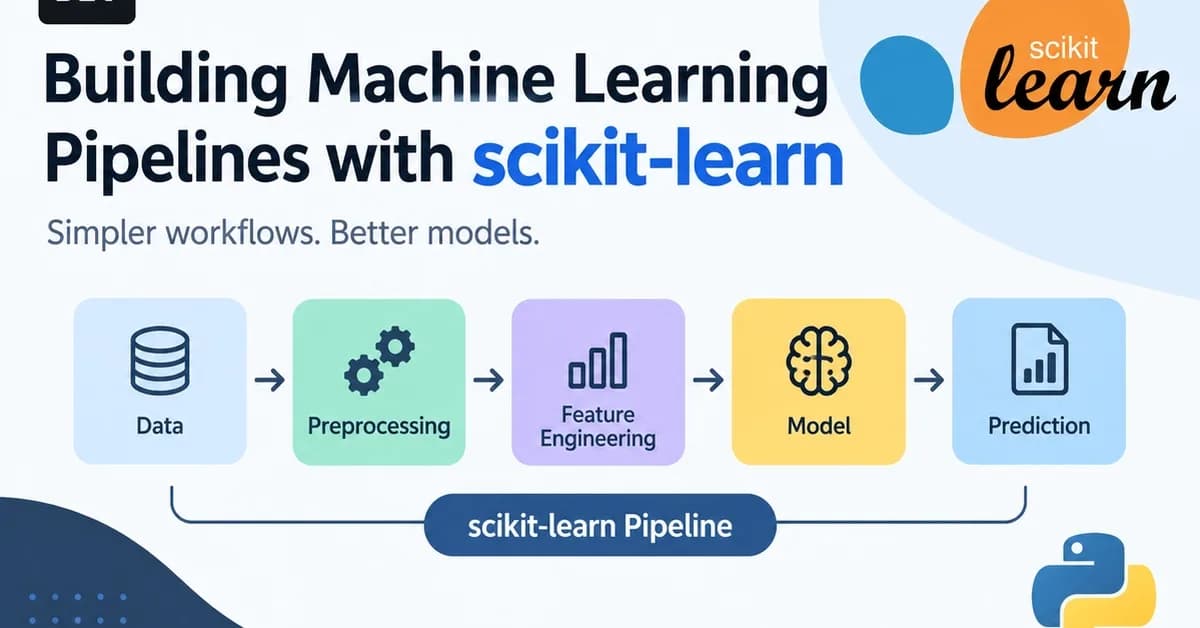
Scikit-learn’s Pipeline feature consolidates data preprocessing and model training into a single, reusable component, preventing common errors like data leakage by ensuring transformations are learned only from training data. This streamlined approach not only simplifies code but also enhances the efficiency of hyperparameter tuning using tools like GridSearchCV.
Developers should be cautious about fitting transformers on entire datasets before splitting them into training and test sets to avoid performance inflation due to information leakage.
Read the full article at DEV Community
Want to create content about this topic? Use Nemati AI tools to generate articles, social posts, and more.
Views31

Ali NematiBlogUI.author_articles