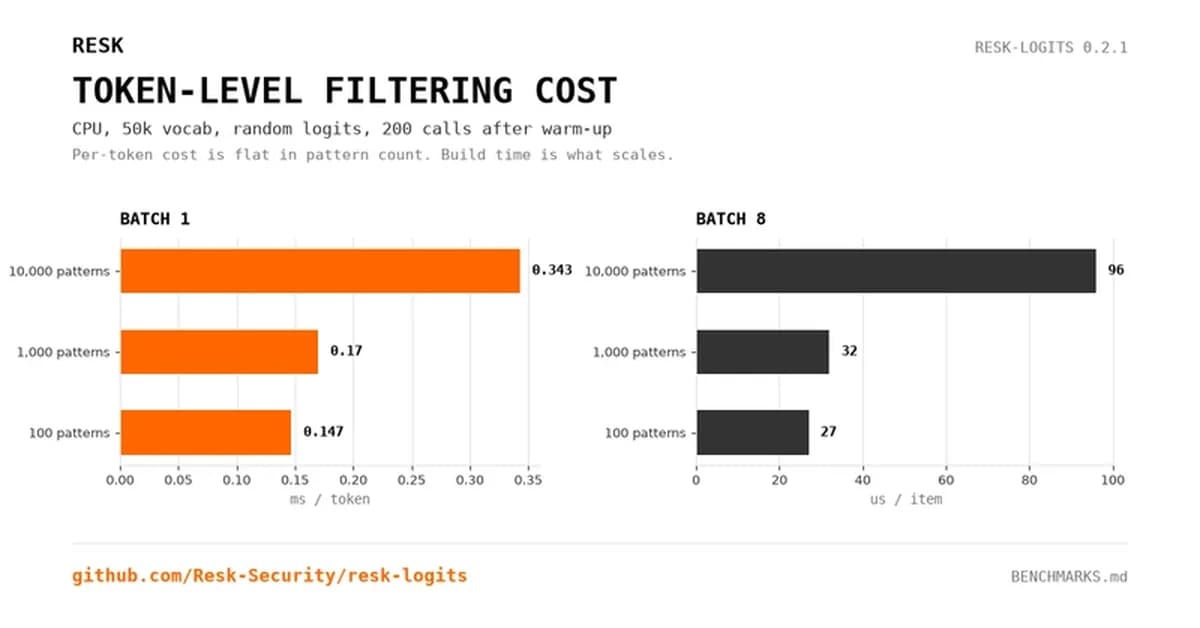
Benchmarking reveals that token-level filtering for banned patterns adds a minimal cost of 0.147 to 0.343 ms per token on CPU, regardless of the number of patterns. This is significant for AI and ML practitioners developing large language models as it quantifies the performance overhead of implementing content safeguards. Developers should monitor advancements in optimizing these filtering mechanisms for even greater efficiency, especially for real-time applications.
Read the full article at DEV Community
Want to create content about this topic? Use Nemati AI tools to generate articles, social posts, and more.
Views0
Tags

Ali NematiBlogUI.author_articles