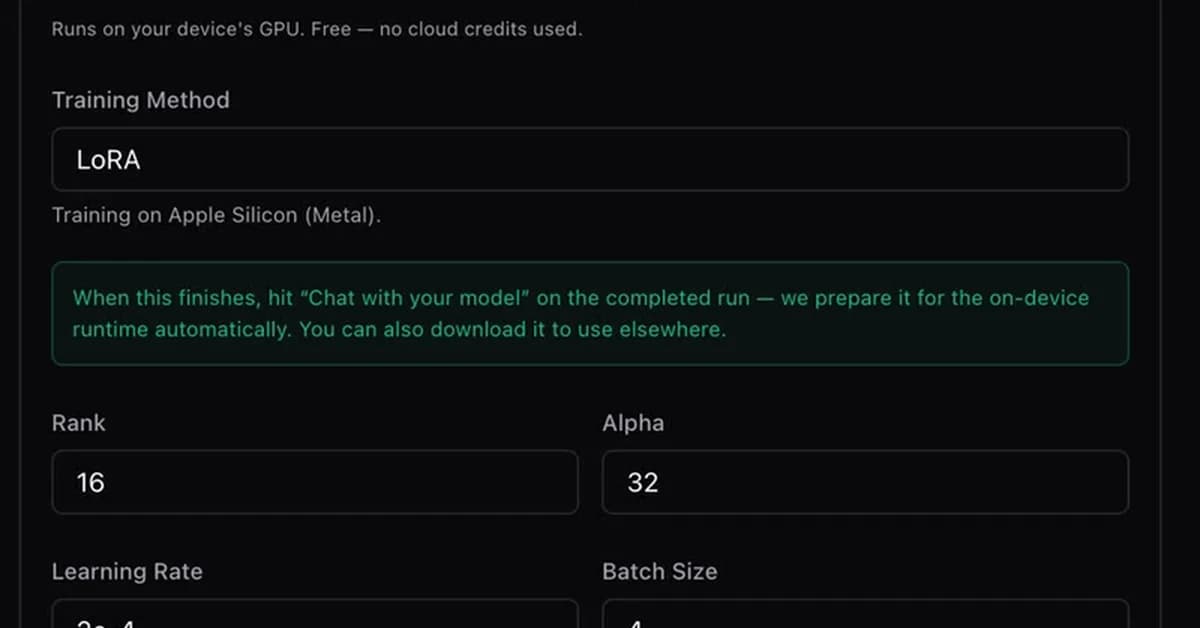
LoRA fine-tuning typically trains only about 1% of a model's parameters, but the specifics of which layers are adapted, the rank used, and the precision of the base weights significantly impact training time and resource requirements. A detailed analysis of a Qwen2.5-1.5B model reveals that most trainable parameters reside within the multi-layer perceptron (MLP) projections, and that memory usage is dominated by the base model's weights. This understanding is crucial for practitioners seeking to efficiently customize large language models with limited computational resources, and it highlights the trade-offs involved in techniques like QLoRA.
Read the full article at DEV Community
Want to create content about this topic? Use Nemati AI tools to generate articles, social posts, and more.