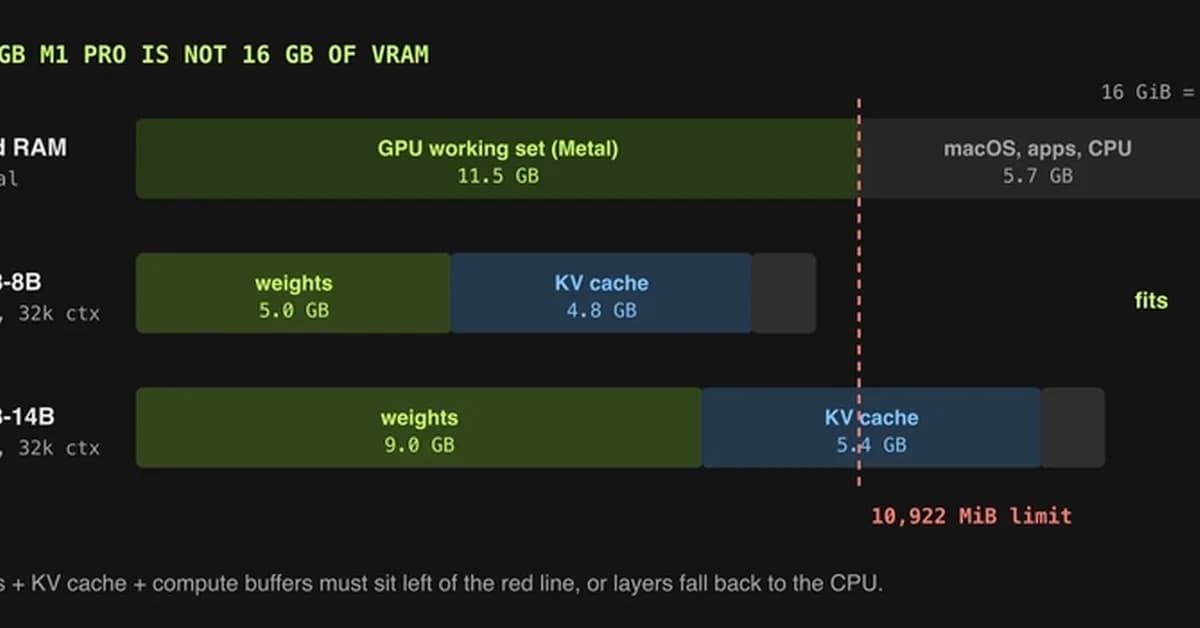
Determining if a large language model will run on a personal computer requires calculating its memory requirements, including weights and KV cache, against available RAM and VRAM. Generation speed is also constrained by memory bandwidth relative to the bytes read per token. Quantization levels significantly impact model size, with lower bit precision fitting larger models but potentially affecting performance on critical tasks like tool calls.
Read the full article at DEV Community
Want to create content about this topic? Use Nemati AI tools to generate articles, social posts, and more.
Views21

Ali NematiBlogUI.author_articles