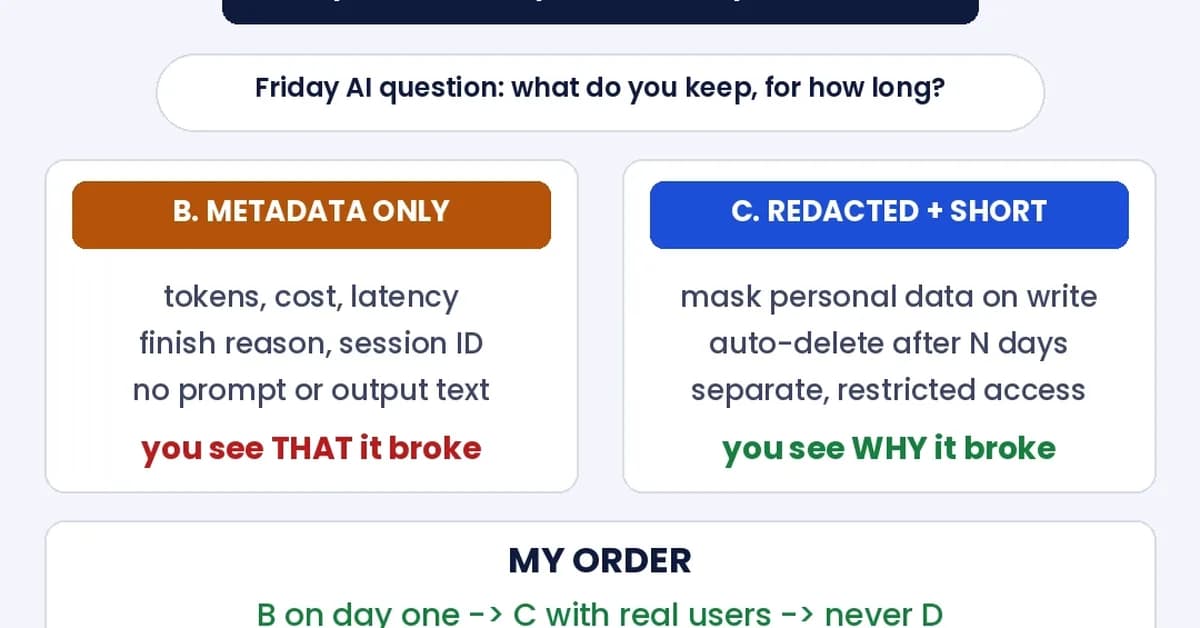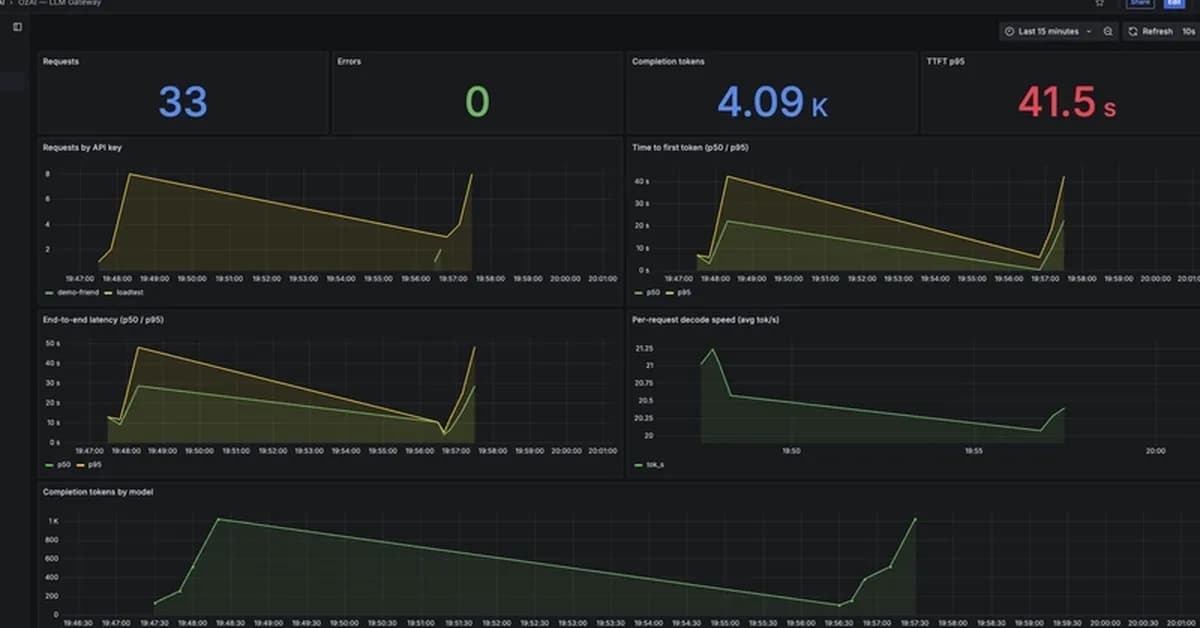
Monitoring a self-hosted Large Language Model requires tracking metrics beyond basic request rates and errors, focusing instead on Time To First Token (TTFT) and tokens per second during generation. The core development is leveraging the existing request logs in a PostgreSQL database to build a custom monitoring dashboard with Grafana, avoiding costly enterprise solutions. Future implications include the need for detailed phase-specific metrics to diagnose performance issues in LLM applications.
Read the full article at DEV Community
Want to create content about this topic? Use Nemati AI tools to generate articles, social posts, and more.
Views0
Tags
Ali NematiBlogUI.author_articles