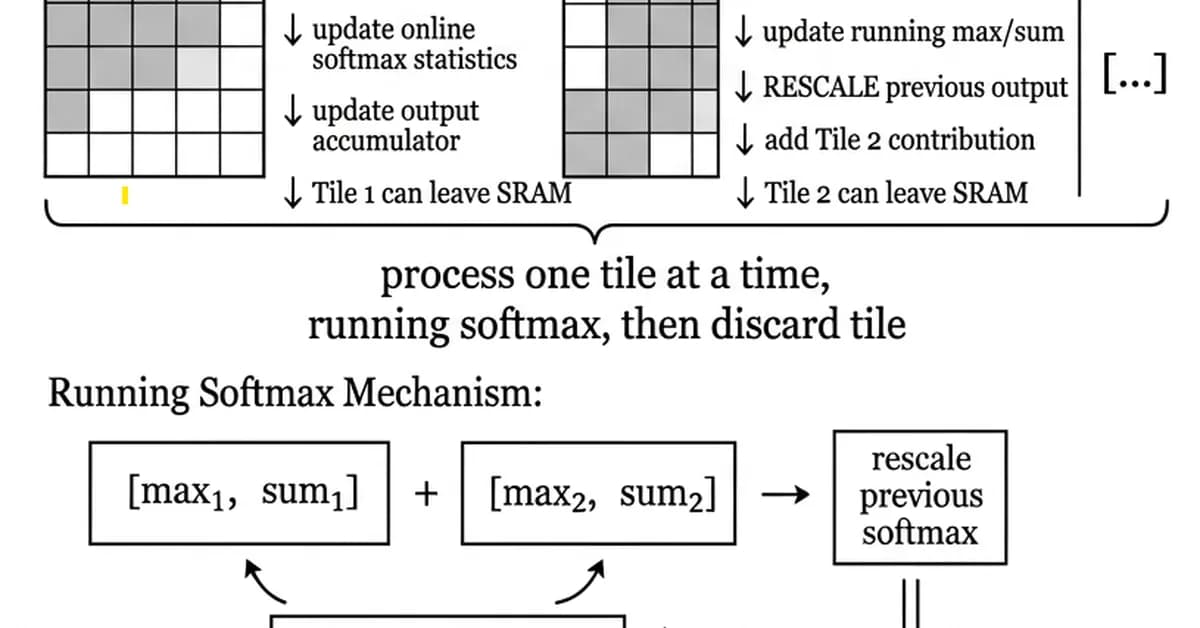
Transformer models, foundational to many AI applications, rely heavily on attention mechanisms to process sequences of data. Recent engineering advancements have focused on optimizing these mechanisms to address limitations encountered when scaling models and handling long sequences. Techniques like Rotary Position Embedding (RoPE) inject positional information, Key-Value (KV) caches reduce redundant computations during generation, and Flash attention minimizes memory bandwidth bottlenecks by avoiding full matrix materialization. These innovations are crucial for improving the efficiency and performance of large language models and other sequence-processing AI systems.
Read the full article at Towards AI - Medium
Want to create content about this topic? Use Nemati AI tools to generate articles, social posts, and more.