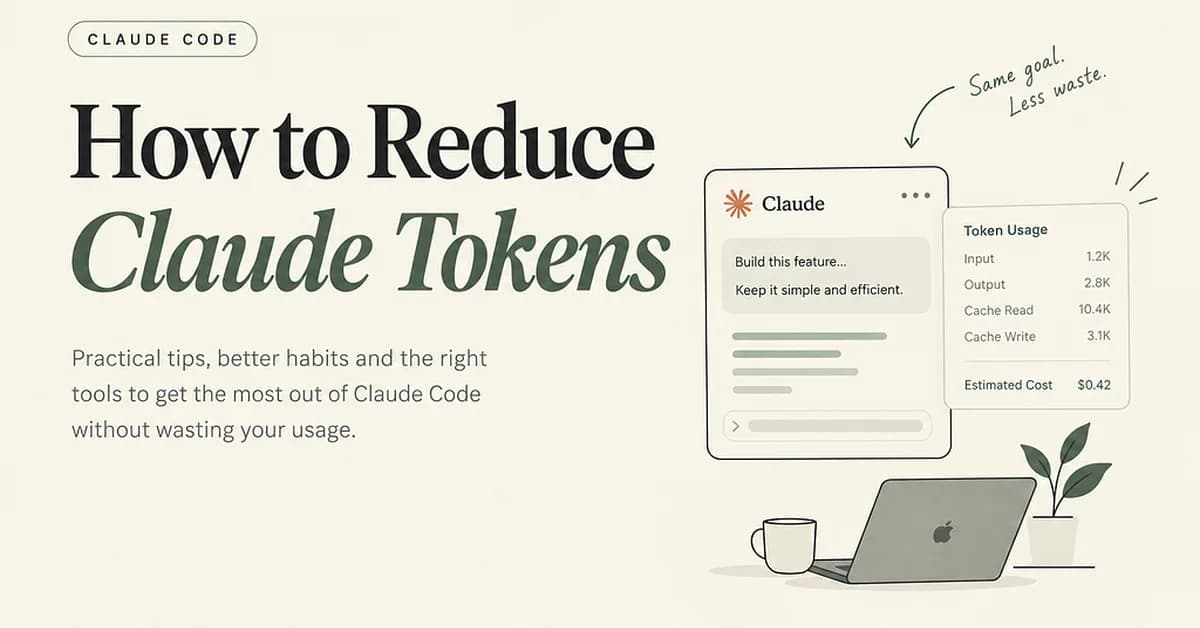
Usage of large language models like Claude can be significantly reduced by understanding that 100% session limit does not equate to a fixed token count. Factors such as model choice (e.g., Opus vs. Sonnet), conversation history, and cached context dramatically impact token consumption and cost. By starting fresh conversations more often and being judicious with context, users can effectively manage their token usage and costs.
Read the full article at Towards AI - Medium
Want to create content about this topic? Use Nemati AI tools to generate articles, social posts, and more.
Views24
Tags

Ali NematiBlogUI.author_articles