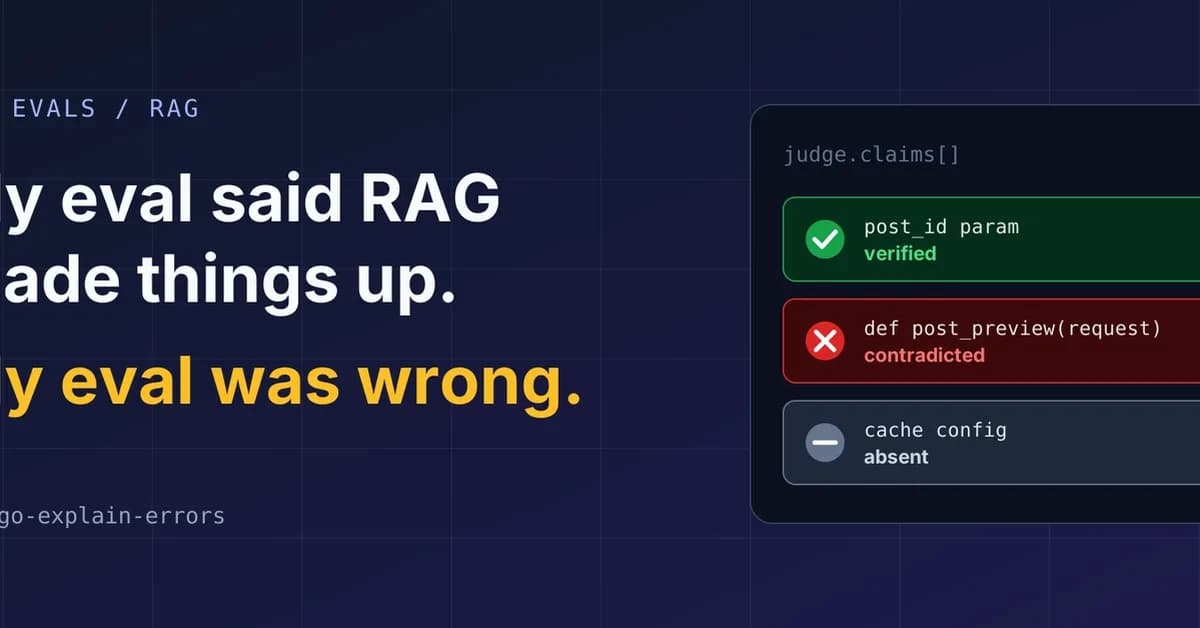
Recent evaluations of Retrieval Augmented Generation (RAG) systems revealed a surprising issue: initially, RAG appeared to fabricate more information than systems without RAG. This stemmed from a flawed evaluation setup where the judge model lacked sufficient context to verify details provided by RAG, leading it to penalize specificity as fabrication. The findings highlight the critical importance of carefully designing evaluation metrics and ensuring judges have access to the same information as the models they are assessing, as subtle biases in evaluation can obscure true model performance.
Read the full article at DEV Community
Want to create content about this topic? Use Nemati AI tools to generate articles, social posts, and more.
Views21
Tags

Ali NematiBlogUI.author_articles