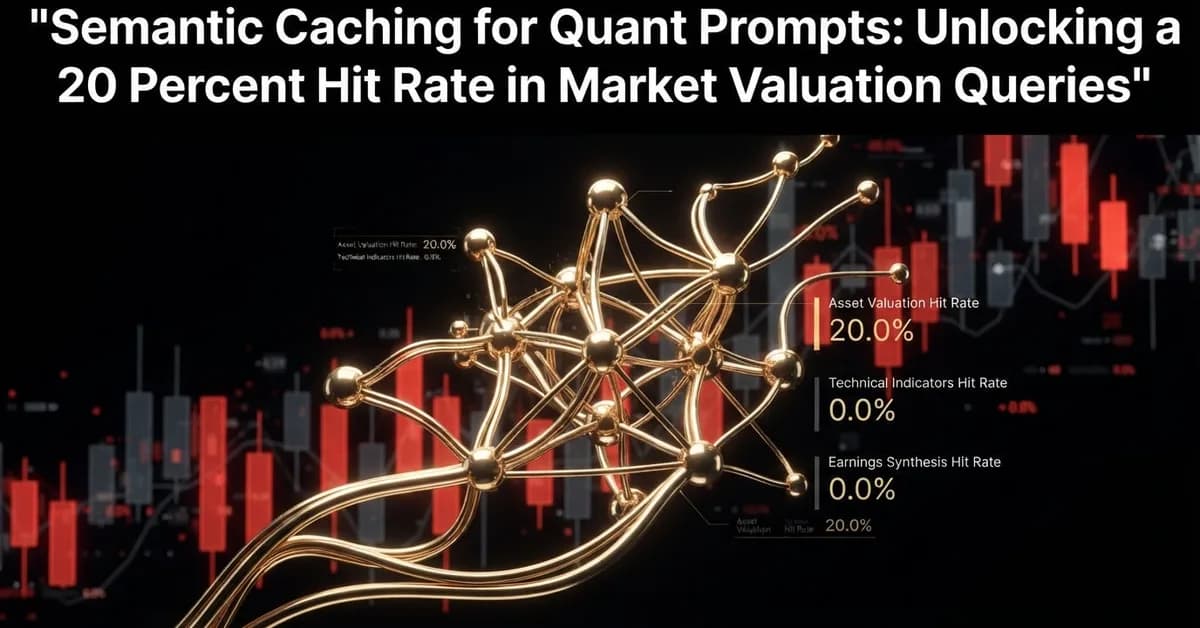
A semantic caching layer using vector embeddings has been implemented to reduce API latency and costs for quantitative finance queries. The system achieved a 20% hit rate for valuation queries by intercepting redundant requests, significantly improving efficiency. This approach leverages AI for initial query understanding and embedding, while static databases handle specific numerical data, balancing nuanced analysis with cost savings.
Read the full article at Towards AI - Medium
Want to create content about this topic? Use Nemati AI tools to generate articles, social posts, and more.
Views23

Ali NematiBlogUI.author_articles