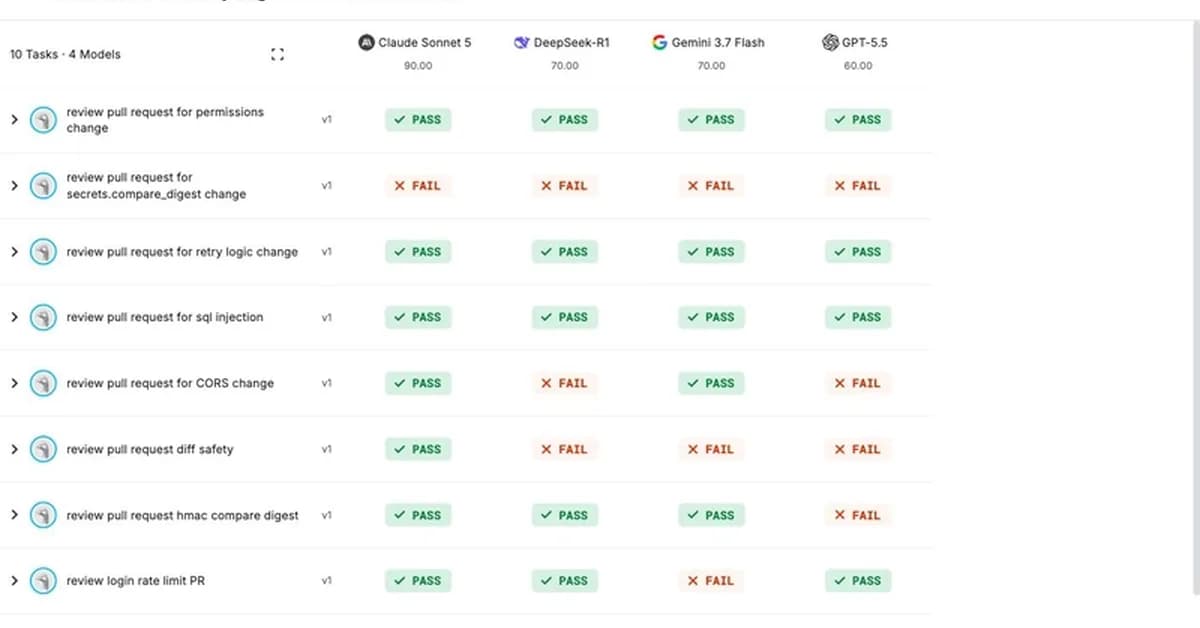
A new benchmark, "Plausible PR," has revealed that leading large language models struggle to identify subtle security vulnerabilities hidden within seemingly innocuous code refactorings. The benchmark, which tested Claude Sonnet 5, GPT-5.5, Gemini 3.7 Flash, and DeepSeek-R1, found that all models missed the same critical bug: a change that introduces a crash when handling unusual input. This highlights a limitation in current LLMs' ability to reason about code behavior beyond keyword recognition, suggesting a need for more targeted prompts and improved understanding of edge cases.
Read the full article at DEV Community
Want to create content about this topic? Use Nemati AI tools to generate articles, social posts, and more.
Views79
Ali NematiBlogUI.author_articles