Based on the content provided, it appears you're discussing how to use Pipeline and ColumnTransformer from scikit-learn for preprocessing data and training machine learning models. The key points covered are:
- Handling Different Data Types: You can create separate pipelines for numerical and categorical features.
- Combining Pipelines with ColumnTransformer: Use
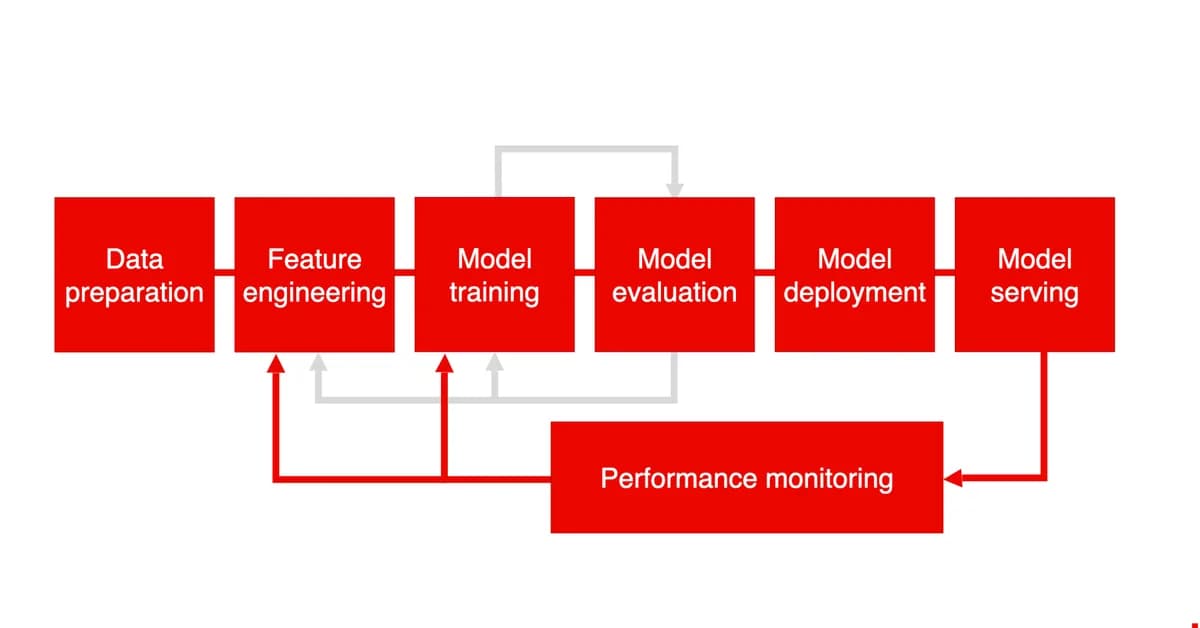
ColumnTransformerto apply different transformations to different columns of the dataset. - Connecting Preprocessing to Model Training: Combine preprocessing steps and model training into a single pipeline, making it easier to manage the entire workflow.
- Hyperparameter Tuning with GridSearchCV: You can tune both preprocessing parameters (like those in
StandardScalerorOneHotEncoder) and model parameters usingGridSearchCV.
Here's an example of how you might set up these pipelines:
python1from sklearn.compose import ColumnTransformer 2from sklearn.pipeline import Pipeline 3from sklearn.impute import SimpleImputer 4from sklearn.preprocessing import StandardScaler, OneHotEncoder 5from sklearn.linear_model import LogisticRegression 6 7# Assuming numerical_features and categorical_features are defined as lists of column names 8numerical_features = ['age', 'income'] 9categorical_features = ['gender'] 10 11# Numer 12 13[Read the full article at DEV Community](https://dev.to/audrine_m/using-scikit-learn-pipelines-a-cleaner-way-to-build-machine-learning-models-2moh) 14 15--- 16 17**Want to create content about this topic?** [Use Nemati AI tools](https://nemati.ai) to generate articles, social posts, and more.
Views9

Ali NematiBlogUI.author_articles