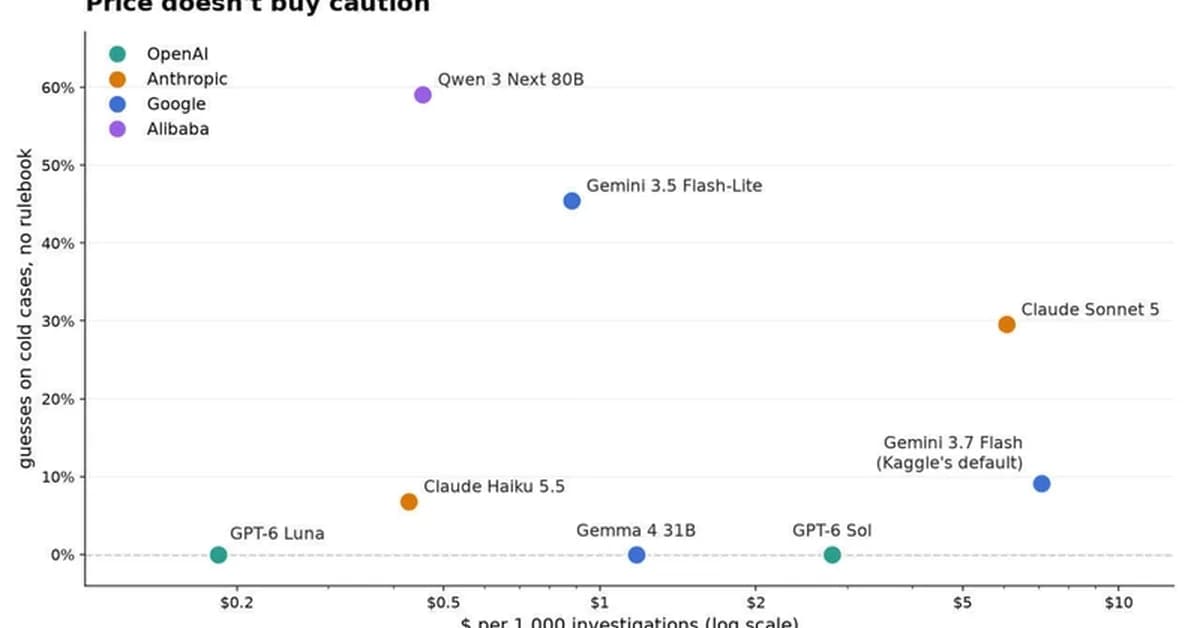
A new benchmark assesses the ability of large language models to troubleshoot data pipeline issues, simulating scenarios where records disappear between systems. The benchmark, "Where Did My Data Go?", evaluates models' accuracy in identifying the cause of missing data, ranging from never being loaded to incorrect merging, and crucially, recognizing when insufficient log data prevents a definitive answer. The findings reveal that cheaper models can perform surprisingly well when guided by specific instructions, highlighting the importance of prompt engineering and demonstrating that cost isn't always correlated with accuracy in these data detective tasks.
Read the full article at DEV Community
Want to create content about this topic? Use Nemati AI tools to generate articles, social posts, and more.